Concept and context
UUIDs are 128-bit identifiers with standardized layouts, but versions encode different information and operational properties.
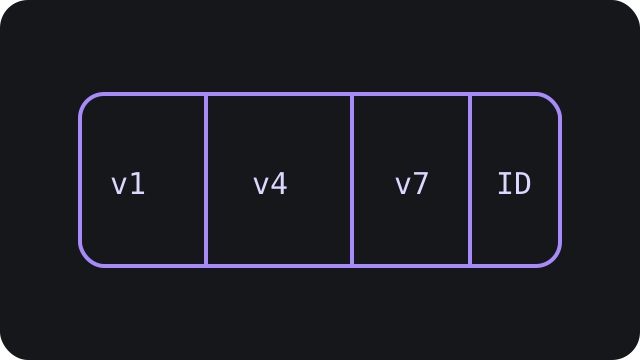
v1 is time-based with historically node-related fields, v4 is random, and v7 combines a Unix-millisecond timestamp with randomized bits.
A sound mental model separates the abstract concept from its concrete representation and from the environment in which it is used. That separation prevents assumptions that are valid for one protocol, library or format from being carried into systems whose rules or guarantees are different.
Fundamentals and terminology
Version and variant occupy fixed bit positions, so not all 128 bits are available as entropy.
UUID v4 still provides a vast random space, while v7 values tend to sort by creation time and can improve insertion locality in ordered database indexes.
Terminology should be read together with the standard, version or contract that defines it, because similar words can describe different properties at different layers. Making those definitions explicit improves interoperability, documentation and the ability to diagnose unexpected behavior.
How it works
Generating v4 requires suitable randomness; v7 builds a timestamp prefix and fills remaining fields with randomness plus rules for multiple IDs in the same millisecond.
v1 uses timestamp and clock-sequence fields and may expose more metadata than an application needs.
In real systems it helps to follow data across layers and identify which transformations are reversible, which introduce constraints and where information can be lost. This makes responsibilities among producers, consumers, storage and transport easier to reason about and test.
Worked example
In a distributed database v4 avoids coordination and makes collisions extremely unlikely, but inserts are random across indexes.
v7 preserves decentralized generation while providing approximate time order, which can reduce fragmentation without turning IDs into a global counter.
A worked example becomes reusable when it exposes its preconditions and invariants rather than showing only an end result. Changing one assumption at a time helps distinguish behavior guaranteed by a standard from choices made by a particular application or implementation.
Errors and misconceptions
A valid UUID does not prove that a resource exists or authorize access, and low collision probability does not remove the value of a database unique constraint.
UUIDs should not be treated as secrets because identification and authentication are separate properties.
Many failures come from implicit assumptions between systems that look compatible while using different versions, canonicalization rules or type models. For interoperability and security, unusual inputs should therefore be specified and tested deliberately instead of being treated as irrelevant edge cases.
Best practices and selection criteria
Choose a version according to privacy, ordering, compatibility and storage behavior.
Generate through standard libraries, use native UUID database types when available and verify byte-order semantics before relying on lexical sorting.
Robust practice combines documented standards, mature libraries, explicit contracts and tests that include representative boundary cases. The best choice is not automatically the shortest or most popular one; portability, readability, performance, security, evolution and operating cost all matter.